 ®
KINEVA® / MODEL TECHNOLOGY
One model family that recognises and explains.
KINEVA® is the model family from REBOTNIX®. Three series work together: visual models recognise what happens in cities and industry. Our language models make this data understandable and answer your questions about it.
Explore the models- KINEVA® / SMART CITY ↗
- For cities: models detect waste dumping, traffic signs and licence plates, and anonymise people. They power REBOTNIX® HORIZON Smart City.
- KINEVA® / INDUSTRIAL ↗
- For industry: models inspect surfaces and detect material defects and foreign objects. They power REBOTNIX® HORIZON Industrial.
- KINEVA® / TRAINING SUITE ↗
- For your own models: develop new models that run on your premises, or evolve existing ones and keep them up to date with maintenance.
- KINEVA® One ↗
- For your questions: our large language models explain visual model results and answer questions about process data in clear language.
10-year lifecycle support for fine-tuning and optimization of our model families.
KINEVA® / SMART CITY
KINEVA® Smart City: for a safe and clean city.
Visual models detect illegal dumping, traffic signs, road damage, unauthorised vehicles and illegally parked vehicles. Further models anonymise people and licence plates.
See models and film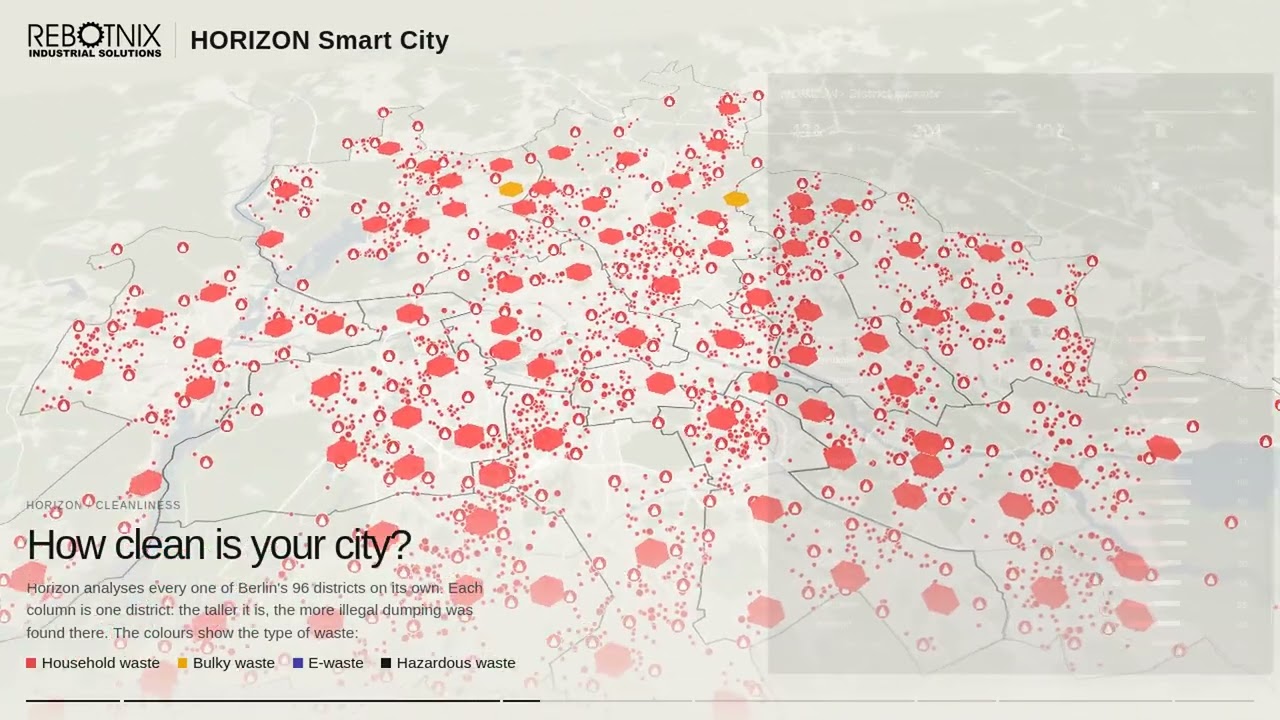
KINEVA® / INDUSTRIAL
KINEVA® Industrial: purpose-built models for anomaly detection.
Each model is trained on one kind of deviation: foreign objects in the material flow, defects on copper plates, metal and sheet metal, or thermal anomalies.
See models and film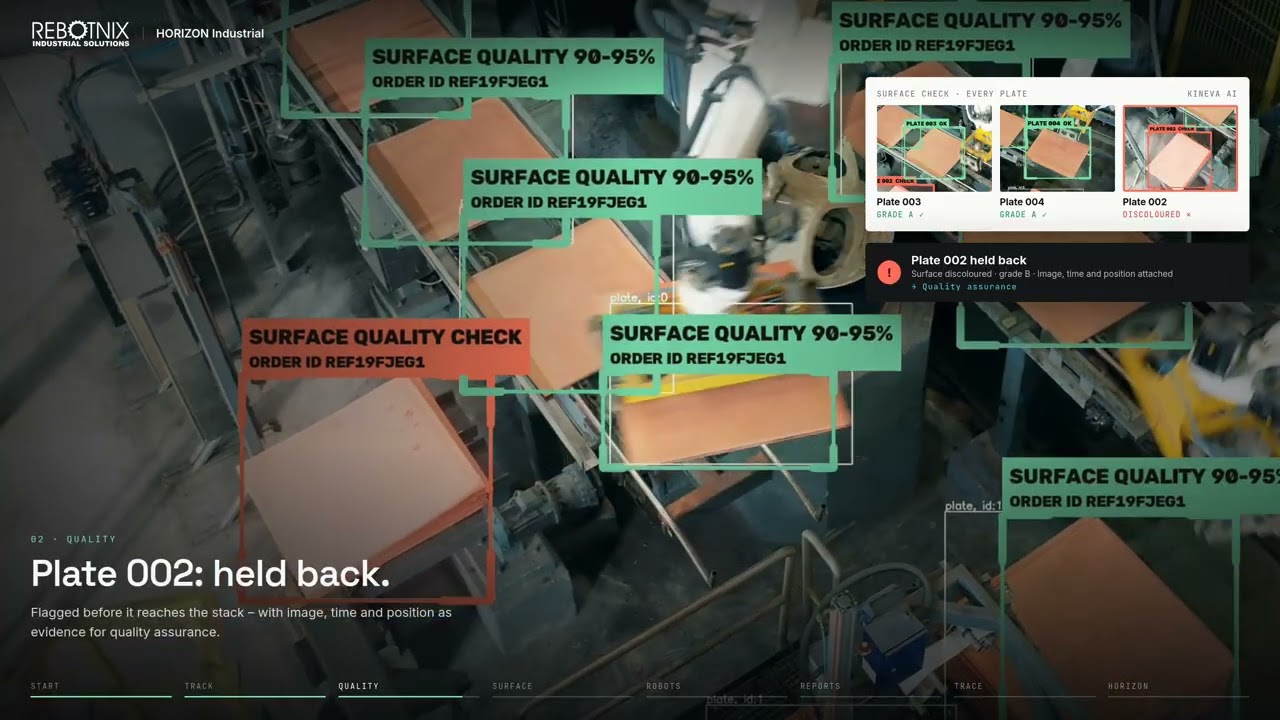
KINEVA® / VISUELLE MODELLE
Visual recognition in a direct comparison.
The demo compares the visual KINEVA® GOLD and SILVER models with YOLO models, showing detection and model execution in real time.
KINEVA® ONE / LARGE LANGUAGE MODELS
KINEVA® One: answers about your process data.
Our series of large language models makes visual model data and other process data understandable. Ask, for example: “Where was the most bulky waste detected this week?” or “How has the number of surface defects changed?” This gives you answers to questions that previously required complex analysis.
KINEVA® One ↗KINEVA® INFERENCE ENGINE
Our own engine for edge and server deployment.
Our own inference engine runs the models in deployment, on embedded edge devices on site or on x86 servers. REBOTNIX® tunes the models, runtime software and hardware to work together.
REBOTNIX® / KINEVA®
Developing our own models since 2018.
Since 2018, REBOTNIX® has been building its own training methods and the KINEVA® Training Suite. This development enables us to train our own model series, fine-tune them for specific tasks and develop them over the long term. Software, training and optimisation come from our own team.
Models, software and hardware, tuned to work together.
We offer matching packages with certified hardware for KINEVA® software. We optimise the models and our inference engine for each system, from embedded edge devices to x86 servers. Training, fine-tuning and deployment are tailored to the application.
Discuss hardware packagesTECHNOLOGY → SYSTEM → OPERATION
KINEVA® models provide the foundation. REBOTNIX® HORIZON uses them in operation.
KINEVA® includes image analysis models and our own language models.
Our large language models make detection results understandable and answer questions about process data and internal knowledge.
HORIZON ↗REBOTNIX® HORIZON uses these models in city and industrial workflows.
KINEVA® / TRAINING SUITE
KINEVA® Training Suite: develop and maintain your own models.
Develop new models that run on your premises, or evolve existing ones and keep them current with maintenance. In-house with the Suite or as a service from REBOTNIX®.
Explore the Training Suite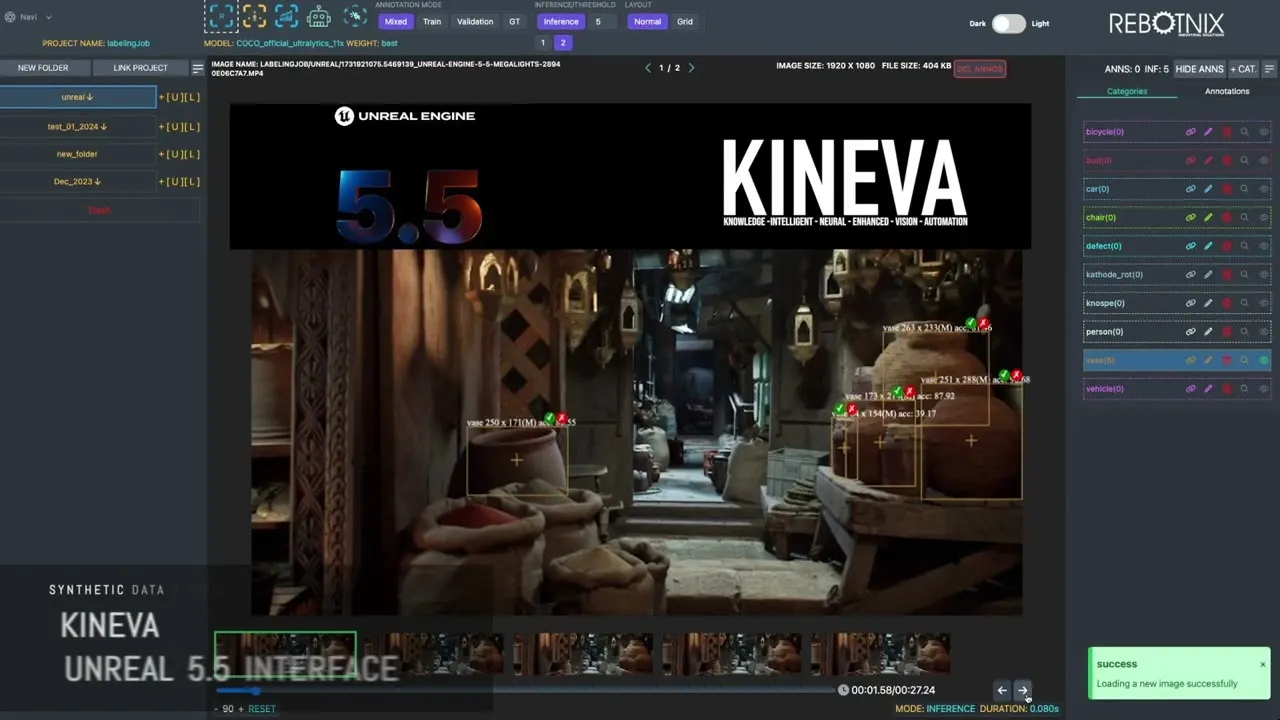
For technical teams
Our model families. Our responsibility.
REBOTNIX® develops image analysis and language models in its own team. We train, maintain and take responsibility for the KINEVA® model families and keep developing them for specific city and industry applications.
Models for the physical world
Language and vision-language models
Our language models use transformer architectures. We fine-tune existing open-weight models or develop and train our own models from scratch. Vision-language models also combine visual information with text.
VLLM / LLM ↗KINEVA® Training Suite
Since 2018, REBOTNIX® has been building its own training methods and the KINEVA® Training Suite. We use this in-house software to train visual models for specific tasks and continuously develop our model series.
Data protection and regulation
Our own models and operations give us control over data flows, changes and responsibilities. This supports implementation of the GDPR and applicable EU AI Act requirements. Whether a specific application meets those requirements depends on its data, purpose and risk classification.