 ®
KINEVA® / FOR TECHNICAL TEAMS
Ask questions of images. Understand results.
Vision-language models help KINEVA® One connect visual findings with questions and other knowledge. They work with specialist detection results.
← Back to KINEVAKINEVA® / Language and vision
How this component works.
Receive detections
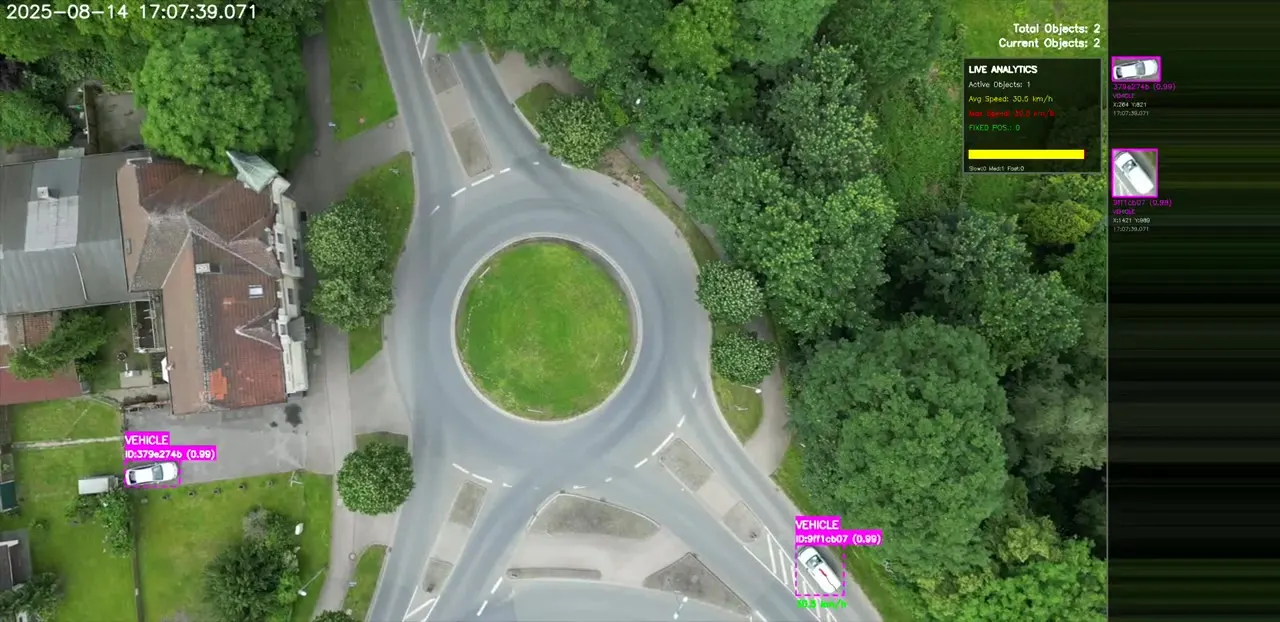
REBOTNIX® models report what a local camera detected.
Connect image and question
KINEVA® One can look at the image more closely when needed and bring in internal knowledge.
Answer in context
The answer relates to the case and can feed back into the HORIZON workflow.
REBOTNIX® / KINEVA®
Part of a maintained model family.
REBOTNIX® develops and maintains its models and tools. GUSTAV brings processing on site, HORIZON connects results to workflows, and KINEVA® One answers questions about the combined data.
10-year lifecycle support for fine-tuning and optimization of our model families.
KINEVA® One ↗KINEVA®
A technical question?
Talk to our team about models, integration and the right place to run them.
Contact the technical team