 ®
The Problem With How Edge AI Usually Gets Sized
If you have moved a working model onto an embedded module, you know the moment. On the workstation it is accurate and fast. On the target it does not fit, the frame rate is short of what the application needs, and the second model was never going to happen.
This is not a limitation of the hardware. NVIDIA Jetson modules have the compute. The problem is that most of the software stack on top of them was never written for a fixed memory budget. Desktop frameworks assume page cache, swap, and a discrete GPU with memory of its own. On a Jetson the CPU and GPU share one physical pool, and every byte a framework holds for convenience is a byte the neural network cannot use.
The usual response is to shrink the model: a smaller variant, INT8, pruning, lower resolution. It works, and it is quick. It also changes what the network outputs, which means the customer's perception model has to be re-tested and, in a regulated domain, re-certified.
We took the other route: we rebuilt the runtime instead of shrinking the model.
Why the Model Is Rarely Where the Memory Is
Before optimizing anything, it is worth knowing what actually holds memory on a Jetson at inference time. We instrumented our own detection process from a cold start through to steady-state inference and measured resident memory at each stage. The workload is a single-stage detector, 640x640 input, FP16 TensorRT engine, 80 classes.
Read the increments, because they reframe the whole discussion.
The FP16 engine on disk is 21 MB. Quantizing it to INT8 would save roughly 10 MB of that, under two percent of a 538 MB process, in exchange for a calibration campaign and an accuracy conversation with the customer.
The two large jumps are the CUDA context with the TensorRT runtime coming up (283 MB), and the warmup allocation (177 MB), which covers activation memory, device I/O buffers, and the CUDA modules loaded on first use. Quantization does not touch the first number at all. It can shrink the activation share of the second, but not the runtime modules and not the context, and on this profile those fixed costs are the bulk of the process. They get smaller when you stop instantiating a second framework on top of them, stop paying for a CUDA context per process, and stop allocating buffers you are not using.
That is where our engineering went.
What We Measured
KINEVA is a native C++ inference engine and rb_vision a native C video pipeline, both written from scratch for Jetson. All figures below were taken on the module named at the top of this document, in full power mode, with tegrastats sampled for the exact duration of each run.
A complete detection pipeline in 501 MB
501 MB peak resident memory for the full path, covering CUDA context, TensorRT runtime, engine weights, video decode, preprocessing, inference and NMS, at 6.92 ms inference per frame: 145 fps inference throughput, 104 fps end to end including H.264 decode on 720p video. Cold start is 1.17 s engine load plus 67 ms warmup, one time.
The detector output is unchanged. No quantization below FP16, no pruning, no resolution reduction. Validated against the PyTorch reference to sub-pixel boxes and three decimal places of confidence.
No interpreter, no ML framework, no media framework on the target. There is no Python environment to pin, no framework version to track across JetPack upgrades, and no dependency drift in the field.
Four models on one module for the price of one and a half
Most real applications run more than one model, and the common pattern is one process per model. On Jetson that pattern is expensive for a reason unrelated to the models: every process pays for its own CUDA context and TensorRT runtime, roughly 350 MB, before a single weight is loaded.
We put four detectors trained in-house into a single process, all warm and routable per frame:
kineva_coco, 80-class general detectionillegalwaste, illegal waste dumpinghead, head and person detectionlicenseplate, licence plate detection
1.4 GB freed on one module, with no change to any model. On a 4 GB module, that difference is the entire deployment.
82 millijoules per inferred frame
Sampled with tegrastats at 500 ms intervals across a continuous 1200-frame run, 104 fps end to end including H.264 decode.
8.5 W of incremental board power at 104 fps end to end is 82 mJ per inferred frame, a figure a fleet planner can multiply out. Dividing by the inference-only rate would flatter that to 58; we report the end-to-end figure, because the end-to-end figure is what the deployment pays. And at 62 % average GPU utilisation the module is not saturated: there is headroom for a second workload on the same silicon, which is what makes a smaller module a realistic target rather than a hopeful one.
One Field Note, Free to the Ecosystem
This cost us real time to find. It is a platform property rather than a method of ours, so we are publishing it.
Set the power mode before you measure anything. Our first dual-stream measurement was taken accidentally in 15 W mode: four of eight cores online, capped at 1.42 GHz. It read 33.5 fps per stream and we concluded the target was unreachable. In full power mode the same code sustains 110.7. One nvpmodel setting inverted an engineering verdict and nearly cost us a product decision.
On Reporting Honestly
Two habits, because they are the reason the numbers above can be trusted.
We publish results that went against our own expectations. Measuring the same engine and the same 300 frames through the native CLI and through the Python bindings gave 501 MB versus 541 MB, a difference of 40 MB (about 8 %) and 1.4 % latency. So the claim "we removed Python and saved gigabytes" is not supported by measurement, and we do not make it. The interpreter is cheap; the framework is expensive. What we removed is the ML framework from the inference path, not the language. The bindings exist so integration code can stay in Python while the memory-relevant part is native.
We also documented two optimizations of our own that measured worse than the baseline and were abandoned on the evidence rather than pursued on the assumption. Both are in the technical report, with the instrumentation behind them.
Why This Comes From REBOTNIX
Three properties fall out of owning the whole stack rather than a layer of it.
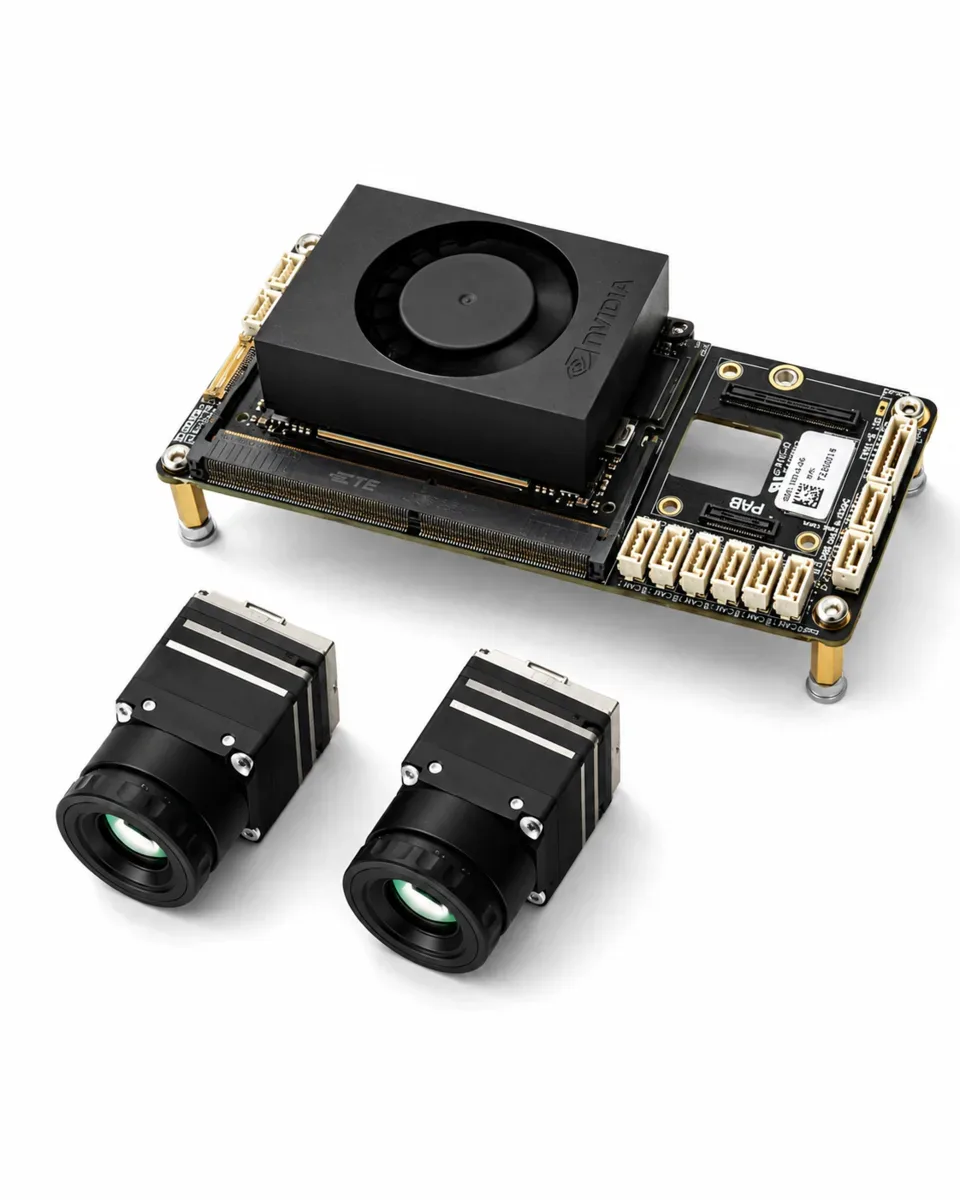
We deliver the complete system, not a component. Camera hardware, carrier integration, the inference engine, the models, the video pipeline, licensing and IP protection, from one source, on one support path. Memory and power behaviour are therefore engineering decisions we can move to fit a customer's budget, not properties of a framework we have to work around.
The models are ours. The four detectors measured here are not a special case. They are a slice of a catalogue that is trained in-house end to end:
- Head / Person Detection
- License Plate Detection
- Illegal Waste Detection
- Waste Category
- Car / Truck Detection
- COCO 80-Class
- Graffiti Detection
- Traffic Sign Recognition
- Face Anonymisation
- WiFi Person Scanner
- Virtual RTK GPS
- Vehicle Detection and Classification
- Aircraft Detection
- Ship and Maritime Detection
- Multi-Sensor Flight Tracking
- Industrial Scene Understanding
- Infrastructure Report Generator
Seventeen models, three families, one runtime. Details at KINEVA.
There is no third-party inference wrapper anywhere in the runtime, so the customer inherits no copyleft obligation from the perception stack. We applied the same reasoning on the video side, selecting a permissively licensed software encoder over the GPL alternative specifically so the product can ship closed-source.
IP protection is part of the runtime. Models ship AES/ChaCha sealed and are decrypted in memory against their registered name; licensing and machine binding are built into the engine, with no OpenSSL on the target.
Request the technical report
This document reports what we achieved. A second document covers how, and is available on request under NDA:
- The eight runtime techniques behind the figures above, each with its measured effect and its trade-off
- The per-frame host staging that was eliminated from the inference path, and how
- Work placement across the SoC, which pipeline stage runs on which engine, and what each move cost or saved
- The two optimizations that measured worse than the baseline, with the instrumentation that showed it
- The residency architecture behind the 1.4 GB, and the reload-versus-resident decision curve
- Full reproduction commands for every measurement in both documents
Working on a Jetson deployment that does not fit the module you budgeted for? The answer is not always a smaller model. Very often it is a smaller runtime. Bring us the workload and the module you want it on.
All figures refer to the configuration named above and may differ with hardware, software revision and workload. Subject to change, errors and omissions excepted.